Leverage Our Experience
Deliver reliable AI infrastructure and operational excellence with our team of AI & HPC experts who have over 3.3 billion hours of GPU runtime management experience.
Sustain Peak Performance
Maximize cluster reliability, efficiency, and performance through cluster optimization, predictive maintenance, 24x7 proactive monitoring, and dedicated on-site support.
Scale Clusters Seamlessly
Grow rapidly without service interruptions or infrastructure scaling roadblocks with support from teams experienced in evolving technical computing environments.
Best-in-Class Architecture
Our Proven Managed Services Delivery Model
Our Managed Services brings deep operational expertise to enterprises, cloud service providers (CSPs), neoclouds, and hyperscalers with our experience-driven delivery methodology. Our approach maximizes uptime, boosts ROI, and streamlines AI infrastructure growth.
Technical Capabilities
Best-in-Class Cluster Management
Clusters at any scale are complex systems requiring specialized expertise across compute, storage, networking, and software domains. Offload the complex operational demands of AI & HPC infrastructure to specialists with over 2.3 billion hours of GPU runtime management experience.
Engagement Leadership
Engagement leaders oversee technical teams to deliver operational excellence and playbook execution.
Cluster Management & Orchestration
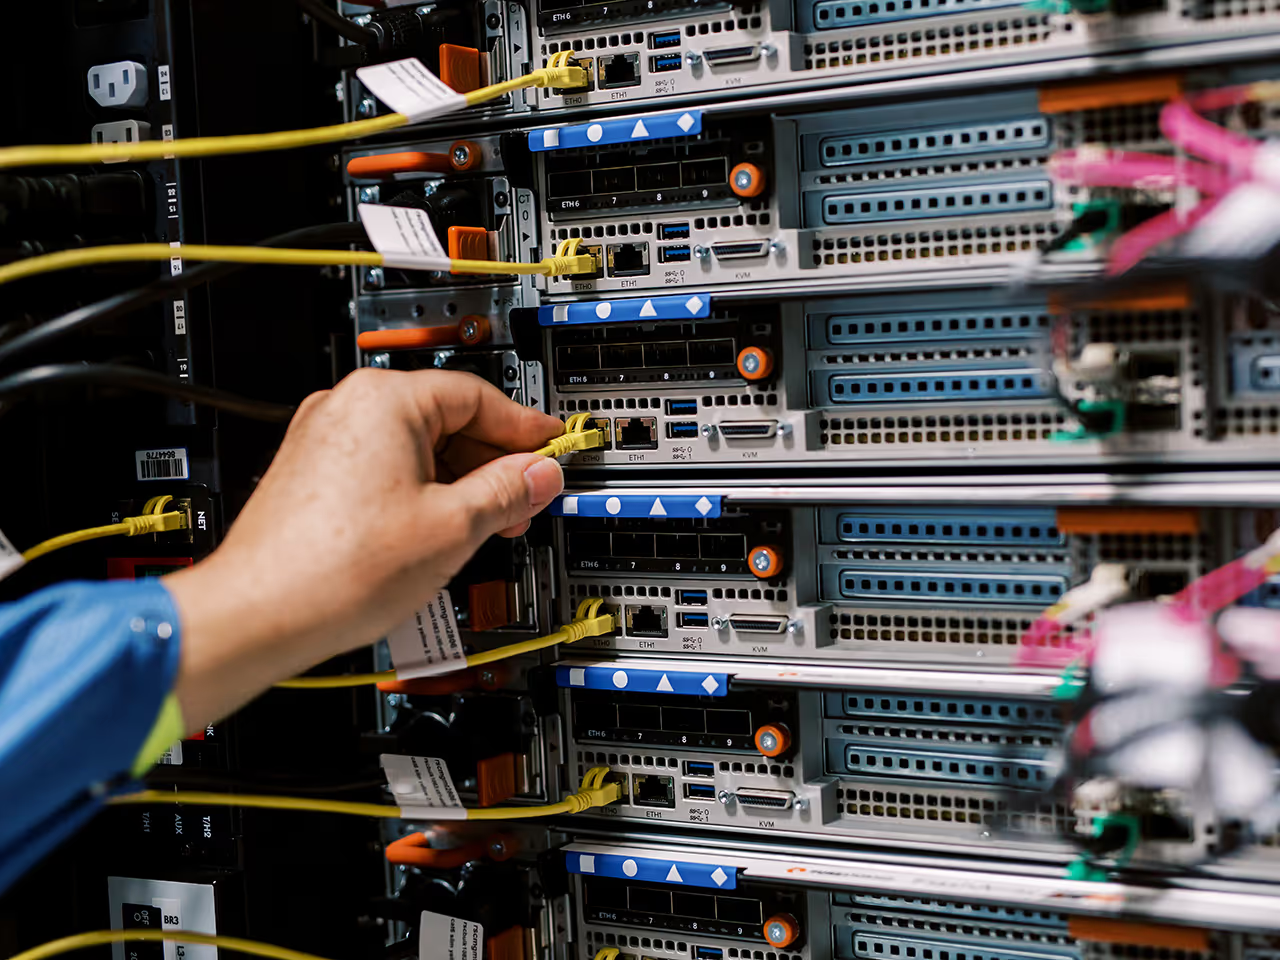
System engineering experts manage the setup, provisioning, and full lifecycle of infrastructure hardware, operating systems, network infrastructure, and storage subsystems.
Onsite or Remote Hardware Support
Our support team delivers continuous system availability and uptime for mission-critical applications, including a local depot of spares to minimize downtime from hardware issues.
Automation & Integration
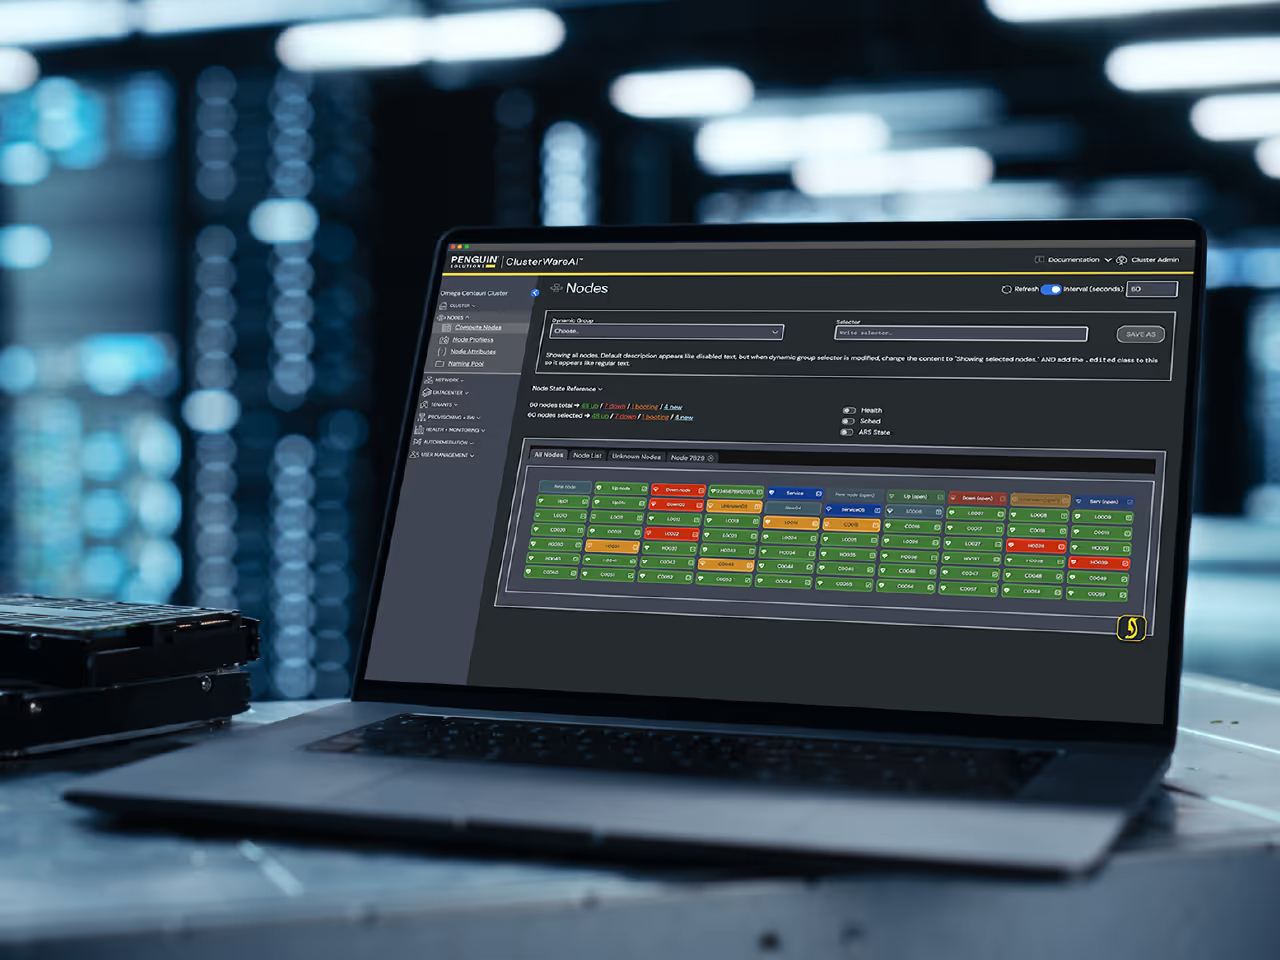
DevOps experts deliver automation to reduce human error, custom monitoring and alerting for proactive issue resolution, and dashboards for full cluster visibility and health.
Asset & Inventory Control
AI and HPC service specialists provide detailed records of deployed assets, secure asset storage, support on-site logistics, coordinate RMA, manage spares, and accurately track inventory.
Change, Incident, & Release Management
Our support team ensures compliance, integrity, and governance of your AI & HPC infrastructure.
Our Process: Additional Services
AI & HPC Infrastructure Comprehensive Services
Penguin Solutions is dedicated to our customers’ success. With 25 years of HPC experience in designing, building, deploying, and managing AI and accelerated computing clusters, we have enabled some of the world’s most sophisticated workloads.