Accelerate your AI applications and scale efficiently with Penguin Solutions' big memory server appliances.
AI system performance for inference is fundamentally constrained by memory. As the complexity of AI models increases and organizations deploy enterprise-scale inference, clusters face the "memory wall"—current limitations in memory capacity and bandwidth, which constrain GPU performance and drastically increase latency.
Penguin Solutions leverages 30 years of experience in advanced memory to solve this problem with breakthrough CXL-based memory servers that enable large pools of shared system memory. This disaggregation frees GPUs from current memory limitations to give each node what it needs, when it needs it, and provides new flexibility and efficiency to cluster architectures.
By deploying abundant, high-performance memory, you can maximize existing GPU investments and efficiently scale new AI infrastructure for enterprise-scale, production inference.
Disaggregated memory is accessible to all nodes, enabling efficient resource utilization and supporting memory-intensive AI workloads.
Delivers consistent, low-latency performance to support demanding real-time AI inference requirements.
Maximize throughput and scalability with balanced memory architecture and reduced compute bottlenecks.
Offload the KV cache to a dedicated, high-capacity CXL-based server, eliminating AI inference memory bottlenecks.
Significantly reduce latency and boost throughput with intelligent KV cache reuse.
Deploy with up to 11 TB of total memory, including an impressive 8 TB of advanced DDR5 CXL memory.
Prevent compute idle time by giving every GPU node fast, shared access to abundant memory.
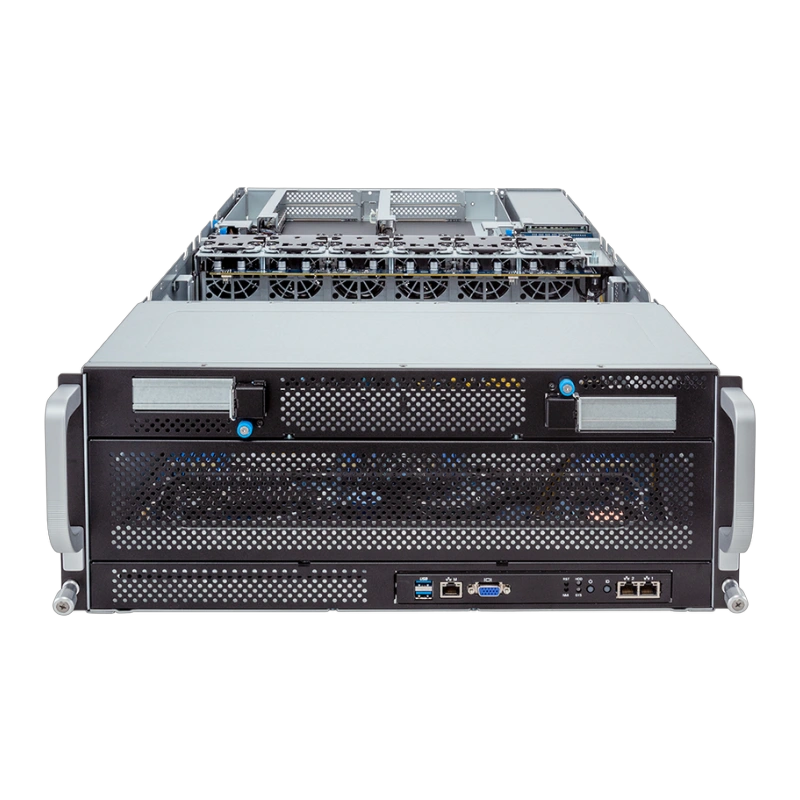
Penguin Solutions' patent-pending MemoryAI KV cache server is the industry's first production-ready KV cache server leveraging CXL memory to deliver a high-capacity memory appliance purpose-built to address the memory wall and support high-performance inference at scale. The KV cache server works by storing and reusing computed key/value (KV) pairs, offloading the KV cache from GPU memory, which eliminates memory constraints, reduces time-to-first-token (TTFT), and addresses re-compute challenges.
Pre-validated CXL memory appliances built for real-time, production-scale AI inference.
Recommended
#MemoryAI KV Cache Server
An Altus-based 4U rackmount KV cache server with up to 11 TB of CXL-based memory.
Our team of experts is ready to help you find the perfect solution for your business needs. Get personalized advice and competitive quotes.
We're here to help with any questions