Details That Matter
Organizations are moving beyond individual AI deployments to AI factories, sovereign AI initiatives, and large-scale AI services that require greater levels of compute, memory, networking, and infrastructure efficiency. As AI workloads scale, organizations need infrastructure that simplifies deployment and operations while enabling large-scale AI environments.
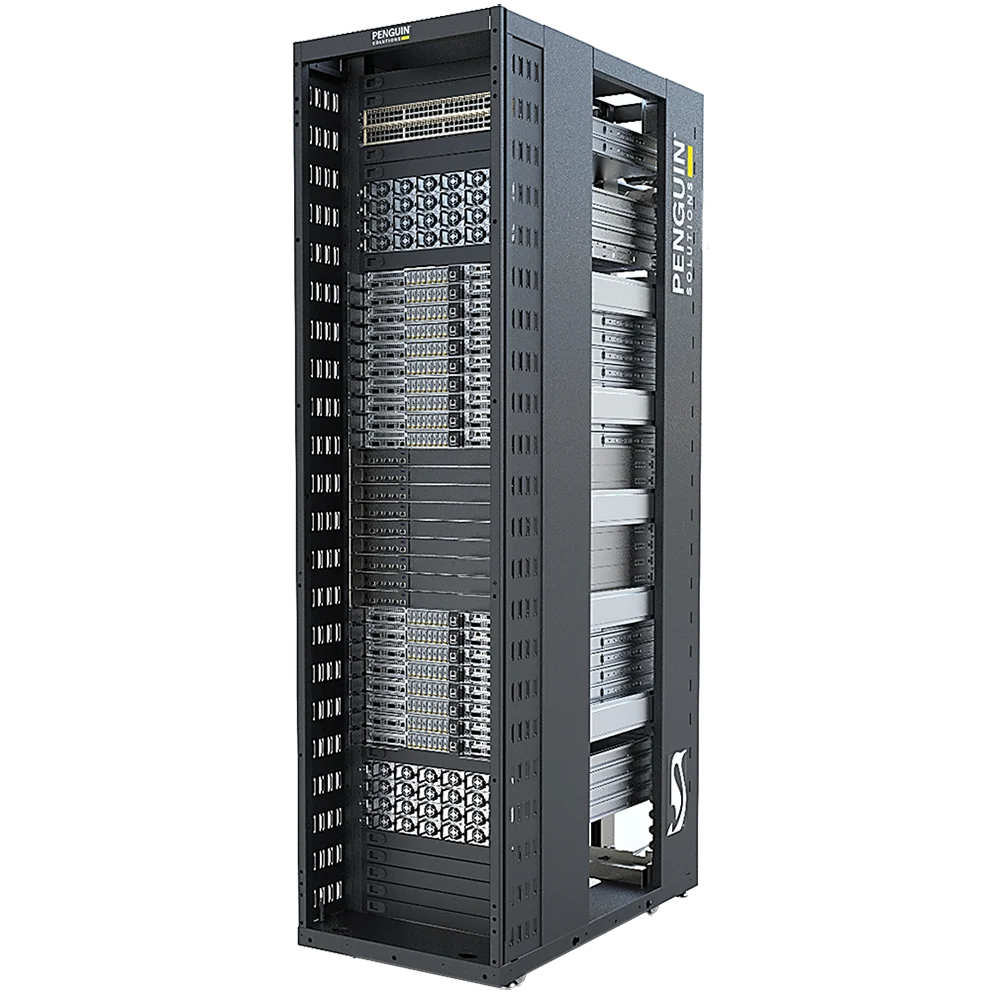
Penguin Solutions ComputeAI NML72-GB300 is a pre-validated, rack-scale NVIDIA GB300 NVL72 platform designed for frontier model training, AI reasoning, and high-throughput inference. By integrating 72 NVIDIA Blackwell Ultra GPUs, 36 NVIDIA Grace CPUs, fifth-generation NVLink switching, rack-level networking, power infrastructure, and direct liquid cooling into a production-ready architecture, the platform helps reduce deployment complexity and accelerate time-to-production for large-scale AI deployments.
Designed for hyperscale AI services, neocloud platforms, and sovereign AI initiatives, ComputeAI NML72-GB300 provides a scalable foundation for organizations deploying AI infrastructure at scale.
Key Capabilities
- Frontier model training and foundation model development
- AI reasoning and high-throughput inference at rack scale
- Sovereign AI, national AI, and hyperscale AI deployments
- Rack-scale AI infrastructure designed to support AI factories
- Direct liquid cooling for high-density NVIDIA Blackwell Ultra deployments
- Rack-scale NVLink fabric enabling high-bandwidth GPU-to-GPU communication
- Pre-validated architecture designed to accelerate deployment and reduce implementation risk
Rack-Scale AI Infrastructure for Strategic AI Initiatives
ComputeAI NML72-GB300 delivers rack-scale infrastructure designed to support strategic AI initiatives from frontier model development to production-scale AI services.
Build Differentiated AI Capabilities
Organizations developing foundation models require massive-scale compute resources capable of supporting distributed model training and ongoing model development. ComputeAI NML72-GB300 provides the infrastructure required for frontier model training and proprietary model development, helping organizations build differentiated AI capabilities.
Deliver AI at Massive Scale
Organizations deploying AI services at scale require infrastructure capable of supporting growing volumes of AI requests while maintaining responsiveness and throughput. ComputeAI NML72-GB300 combines 72 NVIDIA Blackwell Ultra GPUs, fifth-generation NVLink switching, and rack-scale architecture to support AI reasoning and inference for large-scale deployments, helping organizations expand AI services across users, applications, and business functions.
Enable Sovereign AI Initiatives
Governments, research organizations, and national AI programs require dedicated AI infrastructure capable of supporting strategic AI development within controlled environments. ComputeAI NML72-GB300 combines rack-scale compute, networking, and infrastructure efficiency in a pre-validated platform that helps organizations to deploy and operate sovereign AI environments with greater confidence and scalability.
Optimize AI Service Economics
As AI adoption grows, organizations require platforms capable of serving high volumes of AI requests efficiently. By combining high GPU density, direct liquid cooling, and an integrated rack-scale infrastructure, ComputeAI NML72-GB300 supports high-throughput inference environments that help improve infrastructure utilization and optimize the delivery of AI services at scale.
Technical Specifications
Full specifications for ComputeAI NML72-GB300.
Validated L11 Rack-Scale Configuration
| Component |
Validated Configuration |
| Platform |
ComputeAI NML72-GB300 Rack-Scale AI Factory |
| GPU |
72x NVIDIA Blackwell Ultra GB300 GPUs |
| GPU Memory |
20.1 TB HBM3e (279 GB per GPU) |
| CPU |
36× NVIDIA Grace CPUs |
| Host Memory |
17.28 TB LPDDR5X |
| AI Fabric |
5th Generation NVIDIA NVLink Rack-Scale Fabric |
| Network Fabric |
36× NVIDIA ConnectX-8 SuperNIC Ports |
| DPU |
18x NVIDIA BlueField-3 DPUs |
| Management Network |
2× NVIDIA SN2201 Management Switches |
| Storage |
276 TB NVMe Storage |
| OS Storage / Data Storage |
34.6 TB NVMe SSD / 276.5 TB NVMe SSD |
| Cooling |
Direct Liquid Cooling with Integrated Rack Manifold |
| Power |
8× 33 kW Power Shelves, 48× 5.5 kW PSUs |
| Supported Operating System |
Ubuntu 24.04 LTS (ARM64), RHEL 9.x (ARM64), Rocky Linux 9.x (ARM64) |
| Warranty |
3-Year Standard Warranty* |
Documentation
Download product documentation and resources